

If you don't have accurate, scalable, and sufficiently fresh data, along with a semantic layer that can retrieve it quickly, agents are going to take the wrong actions.
 Aditya RanjanSenior Data Engineer
An inventory report may be correct in the morning but can be outdated by afternoon. This happens after customers place orders and stock changes. An employee asking an AI assistant about available products can verify its answer before acting, while an autonomous agent might use the same stale figure to ship, cancel, or amend an order. As AI agents begin making operational decisions, companies must ensure they have reliable data to act on.
Aditya Ranjan is a Senior Data Engineer with more than 16 years of experience across enterprise data warehousing, cloud migration, and real-time analytics. Having worked through successive changes in data architecture, he worries that systems designed for reporting may struggle to support agents making decisions as business conditions change.
“If you don't have accurate, scalable, and sufficiently fresh data, along with a semantic layer that can retrieve it quickly, agents are going to take the wrong actions,” Ranjan warns. His concerns go beyond data accuracy to how companies provide agents with information, control what they can access, and decide which actions they can take independently.
Reporting refresh schedules can be too slow for agents
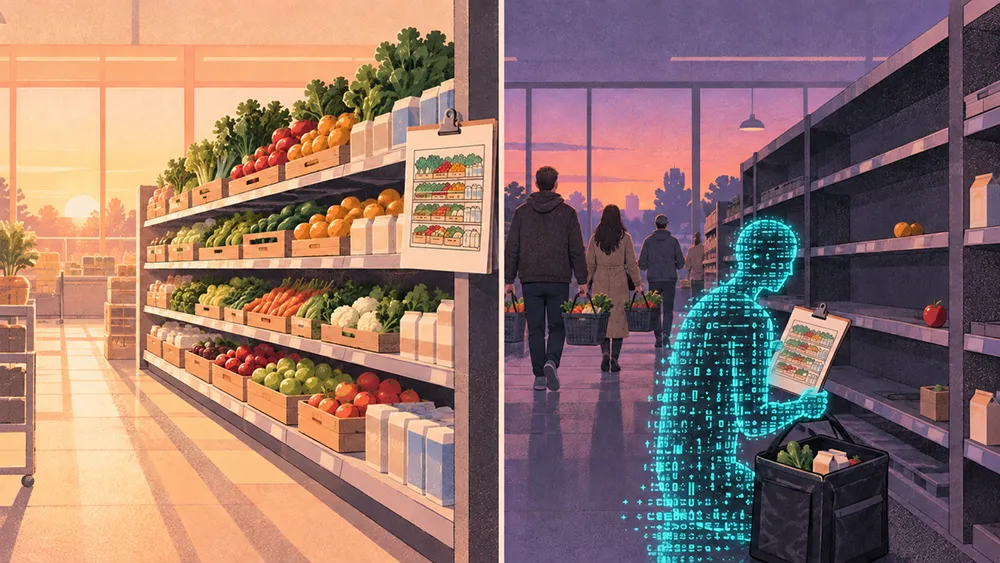
Data that is current enough for a dashboard may already be outdated by the time an agent uses it to fulfill an order. Grocery inventory changes throughout the day as customers buy products and staff restock shelves, making it risky for agents to rely on reports generated hours earlier. “You can't rely on the inventory number remaining the same throughout the day because the agent has to take action based on that number,” Ranjan explains. Even if an agent correctly evaluates whether an order can be fulfilled, it may make the wrong decision because the inventory data no longer reflects what's available.
The need for fresh data becomes even more business-critical when retailers offer one-hour delivery, as Ranjan points out using Walmart as an example. With such tight delivery windows, outdated inventory figures can lead to incorrect fulfillment decisions. “So the data has to be refreshed frequently. But you also need to be cautious about how quickly you want to refresh and access the data,” he says. Companies must therefore balance how often they update their data with how quickly business conditions change and what decisions agents need to make.
Agents need trusted data they can interpret and trace
Refreshing data more frequently won't help if the information is inaccurate or difficult for agents to interpret. Ranjan argues that agents also need clean, consistent data with clear business context, while engineers need a way to trace the source of incorrect decisions. “When quality comes into the picture, you also need a good semantic layer and good data lineage so that if anything goes wrong, a data engineer or staff engineer can go back and see what happened,” he says. A semantic layer provides consistent business definitions and context so agents can interpret data correctly, while timely retrieval depends on the underlying data architecture. Lineage allows engineers to trace the data behind a decision.
Companies must also control what sensitive information agents can access. Ranjan warns that personally identifiable and health-related data could be exposed when agents are connected to multiple applications. “We have to maintain complete governance over the data and let the agent act as a consumer of that data, without giving it unnecessary privileges across the platform,” he says. This means companies must ensure agents receive accurate information while limiting their access to only the data they need.
The consequences of a decision should determine autonomy
Even with accurate, up-to-date data and proper controls, AI agents can make mistakes. Ranjan therefore believes companies should consider the potential harm of each decision before allowing agents to act independently. “We cannot allow everything to be handled by agentic AI or agents themselves,” he says. While agents may handle low-risk internal tasks with little human involvement, decisions affecting customers, sensitive information, or finances may need closer human oversight.
Ranjan calls this approach risk-based autonomy. “Based on risk-based autonomy, we have to determine what human oversight we can provide,” he explains. Rather than applying the same approval process to every AI action, companies should decide when human review is necessary based on the risks involved.
Data leaders must govern the path to autonomy
Companies can begin by testing AI agents on smaller tasks and improving their data systems before allowing agents to make more important decisions. Ranjan has seen these systems evolve from older platforms to cloud-based and distributed architectures, and he believes further changes will be needed as companies adopt AI agents. “But with smaller use cases, we can go ahead and experiment with them,” he says. These early tests can help companies identify problems with data freshness, accuracy, and access controls before giving agents more responsibility.
Ultimately, preparing data for autonomous action requires decisions that extend beyond individual engineering teams. Leaders must determine what information agents can trust, which records they can access, and when people should review their actions. “Data and AI leaders have to step up and put a proper framework or model behind these agents and how they work,” Ranjan says.