
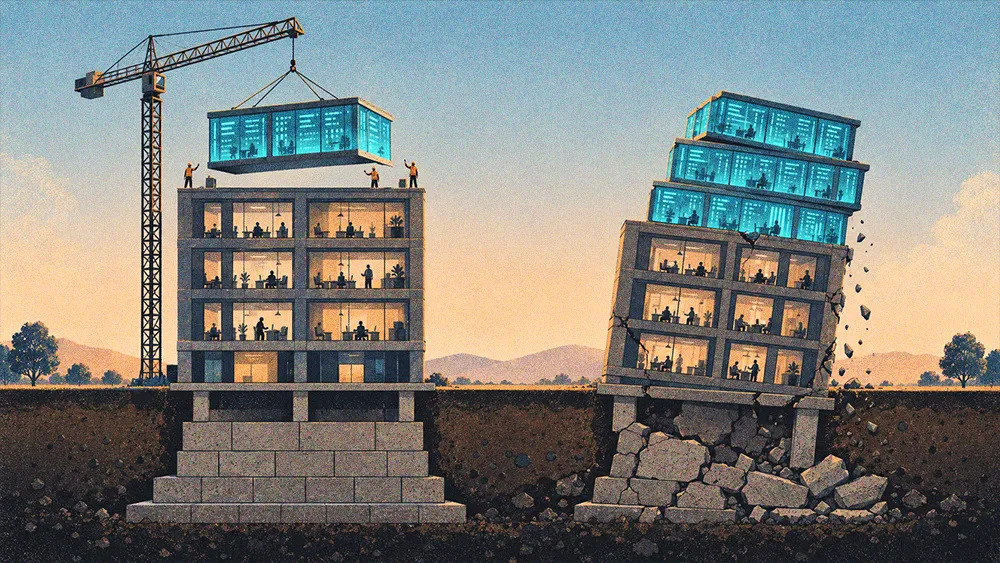

Connecting AI to a mess means you get a really messy outcome. Where you do embed AI, it needs to be thorough. Consistent, with full attention to detail all through the chain, from the source until the solution.
 Søren Meincke PerssonDirector, Data Platform & Governance | AI & Data, Norlys
The appealing version of enterprise AI is the one where you leave your existing data architecture in place and add intelligence on top, like a finishing touch. The objection to such an approach is simple: a finishing touch inherits whatever is underneath it. Layer a capable model over fragmented, inconsistent data and you don’t get a smarter organization. You get fragmentation and inconsistency delivered faster and with more confidence. The work that makes AI trustworthy is the unglamorous work of the foundation, meaning how data is sourced, defined, owned, and connected before any model touches it, and there’s no shortcut around it.
Working through that challenge is Søren Meincke Persson, Director of Data Platform & Governance at Norlys, Denmark’s largest integrated energy and telecommunications group. The company, which serves roughly 3.5 million customers with around 4,700 employees, runs Denmark’s largest electricity grid and fiber network. A recent wave of acquisitions and restructuring, including the integration of Telia Denmark and the mergers that formed the group, gave Persson’s team something most enterprises never get: the chance to rebuild the data foundation from scratch, deliberately designed, as he puts it, for humans and machines alike. That rebuild was possible because of the restructuring, and his advice is aimed at the many companies that can’t start over. That vantage point makes him direct about what the foundation is actually for.
“Connecting AI to a mess means you get a really messy outcome. Where you do embed AI, it needs to be thorough. Consistent, with full attention to detail all through the chain, from the source until the solution,” he says.
You don’t have to tear it all down
For all his insistence on the foundation, Persson is explicit that rebuilding everything is neither necessary nor the point. The scale of the problem changes with the size of the organization. A small company can get away with less rigor. An enterprise where thousands of people consume the same AI solution can’t, because the same question asked slightly differently returns subtly different answers unless the data underneath is solid. His advice for anyone without the luxury of a clean rebuild is to pick one area and do it properly. “Take finance, for example, and do that really solid, to get reliable outcomes from your AI,” he says. Start where the value is, prove the foundation there, and build outward.
Part of doing it properly, in his account, is resisting the urge to feed the model everything. A foundation designed for one era of use often doesn’t fit the next, whether in update frequency, response time, or sheer volume, and more data isn’t automatically better. “The more data you have onboarded makes it less suitable, because the more data, the more difficult it is to find the right answer,” he explains. The discipline is deciding what you actually want out of the data rather than exposing all of it and hoping the model sorts it out.
The questions don’t stop at the dashboard
One shift Persson has watched change the stakes is that people no longer stop asking at the first answer. A dashboard used to be where curiosity ended: a number looked strange, someone wondered why, and that was often as far as it went. Conversational AI invites the follow-up, and expects an answer.
That makes the connections between domains, like finance to sales or one dashboard to another, something the foundation has to establish on purpose rather than leave to chance. Otherwise the system will happily link things that have no business being linked. “You see two graphs rising at the same time but they have no correlation. You don’t want to go there,” he notes. Preventing that means building the real relationships between data into the foundation, so the links an analyst used to make by intuition are ones the system already knows.
Metrics first, from the top down
How Persson decides whether a foundation is ready for a new use case is deliberately structured: he starts from the metric, not the data. His team begins with the top-level metrics the business already trusts, then maps the facts and dimensions each one depends on. From there, they work down a metric tree, with revenue linking to sales and cost, and each of those trickling toward the operational layer, which grows more complex the deeper it goes. Everything operational is derived from the metrics at the top. “We try to go very structured with this,” he says, while freely admitting the approach doesn’t make the problem easy, only tractable.
That structure is also what finally gave data governance something real to do. Governance at many organizations, Persson notes, has long been the function that produces guidelines, org charts, and PowerPoints that never touch the platform. Tying governance to owned metrics changes that. “Now they actually have a group of definitions that they need to maintain and make sure are approved and get out into our AI solutions.” Stewardship stops being a document on the side and becomes something embedded in the solution itself, which is also when the people doing it start to understand why their role matters.
Governance that runs in the platform
For Persson, the test of governance is whether it’s enforced by the platform rather than described in a policy. With a classic medallion architecture running to thousands of tables, manual stewardship is a non-starter. Tagging can’t be a step someone remembers to do downstream. The principle Norlys is working toward is fixing it at the point of entry and carrying it automatically from there. “You need ownership at the source, and then propagate it down through ops all the way to the exposure layers,” he says, and the same holds for GDPR and personally identifiable information, where in Europe the cost of getting it wrong is not theoretical. The only way that scales is programmatically, both for ownership and for who’s allowed to access each area of data.
The human checkpoints matter too, but Persson frames them as a phase rather than a permanent fixture. Keeping a human in the loop is valuable while a team is still learning how a new technology behaves, when the instinct is mostly about not losing control. “If you understood the guardrails you need to set up, then the human in the loop is not necessary,” he says, though he’s candid that it takes time to get there. Norlys started, like everyone, with use cases that kept a human’s final say, and is now starting to move toward autonomy in selected use cases, where the job becomes monitoring and making sure the guardrails hold.
Freshness where it earns its place
The instinct to make all data live, Persson asserts, deserves the same scrutiny as the instinct to feed the model everything. Analytics was built around scheduled pipelines and dashboards, and for most reporting, data that updates every few hours is perfectly fine. “People always want live data, until you ask them why,” he points out. “And usually there’s no apparent reason.” Where there is one, such as order or consumption data on charging solutions, where someone genuinely has to act quickly, the freshness is worth the cost and sometimes warrants a pipeline off to the side. His team leans on dbt and state-aware scheduling to update only the flows that actually have fresh data, rather than running everything on a fixed timer, which makes selective freshness far cheaper to operate.
The reason all of this pays off, Persson says, is that the alternative is a standing tax. Doing the foundational work up front frees the time otherwise lost to fixing broken pipelines and arguing over which number is right when two dashboards disagree. “The investment you make now pays back quite soon,” he says, because the operational burden shrinks when the solutions underneath are solid. He’s relaxed, too, about the fate of the old systems. Norlys still runs its legacy BI alongside the new platform, and he doesn’t expect to need a grand migration plan to retire it. He expects people to move to conversational interfaces by choice, because they get more value there, and as they do, whole areas of the old tooling will fall out of use on their own. Retiring them then becomes a matter of pulling the plug rather than mounting a project.